

The most impressive AI demo I’ve ever seen ended in a production disaster.
A robotics company I won’t name showed me their manipulation model running flawlessly, tying surgical knots in simulation with sub-milimeter precision. Eighteen months of research. World-class team. The model worked.
Then they tried to deploy the model to their actual robots.
Six months later, they were still debugging. The model that ran perfectly in the cloud choked when touching real silicon. Timing issues, memory constraints, thermal throttling, sensor calibration drift. The neura
l network was fine. The hardware was fine. The boundary between them was a disaster.
That company raised hundreds of millions of dollars. And they lost half a year to a problem that has no name, no category, no solution on the market.
This story repeats across every industry building physical AI. And nobody’s talking about why.
Not-so-subtle disclosure: I've written about infrastructure bottlenecks for years on CipherTalk. This one is different. My cofounder and I started Cosmic Labs to build what this essay describes. Consider this the thesis.
The Language Problem
Something most people in tech don’t realize is that software and hardware ‘speak’ completely different languages. Not programming languages, but the fundamental way they communicate.
When your web app talks to a server, the conversation happens in clean abstractions. HTTP requests, JSON payloads, REST APIs… the underlying complexity hides behind decades of infrastructure investment. You don’t think about packets or TCP handshakes or routing tables. You call a function and get data back.
When AI needs to talk to hardware (a GPU cluster, a robot’s motor controller, a vehicle’s sensor array), the abstractions disappear. The “conversation” happens in something closer to native electrical signals: precise timing requirements, register-level commands that vary by manufacturer and chip revision, protocols designed in the 1980s that never anticipated modern AI workloads.
Those “clean abstractions” exist because someone built them.
An abstraction is a layer that hides complexity. Instead of managing every detail directly, developers interact with a simplified interface and trust the layer beneath to handle the rest.
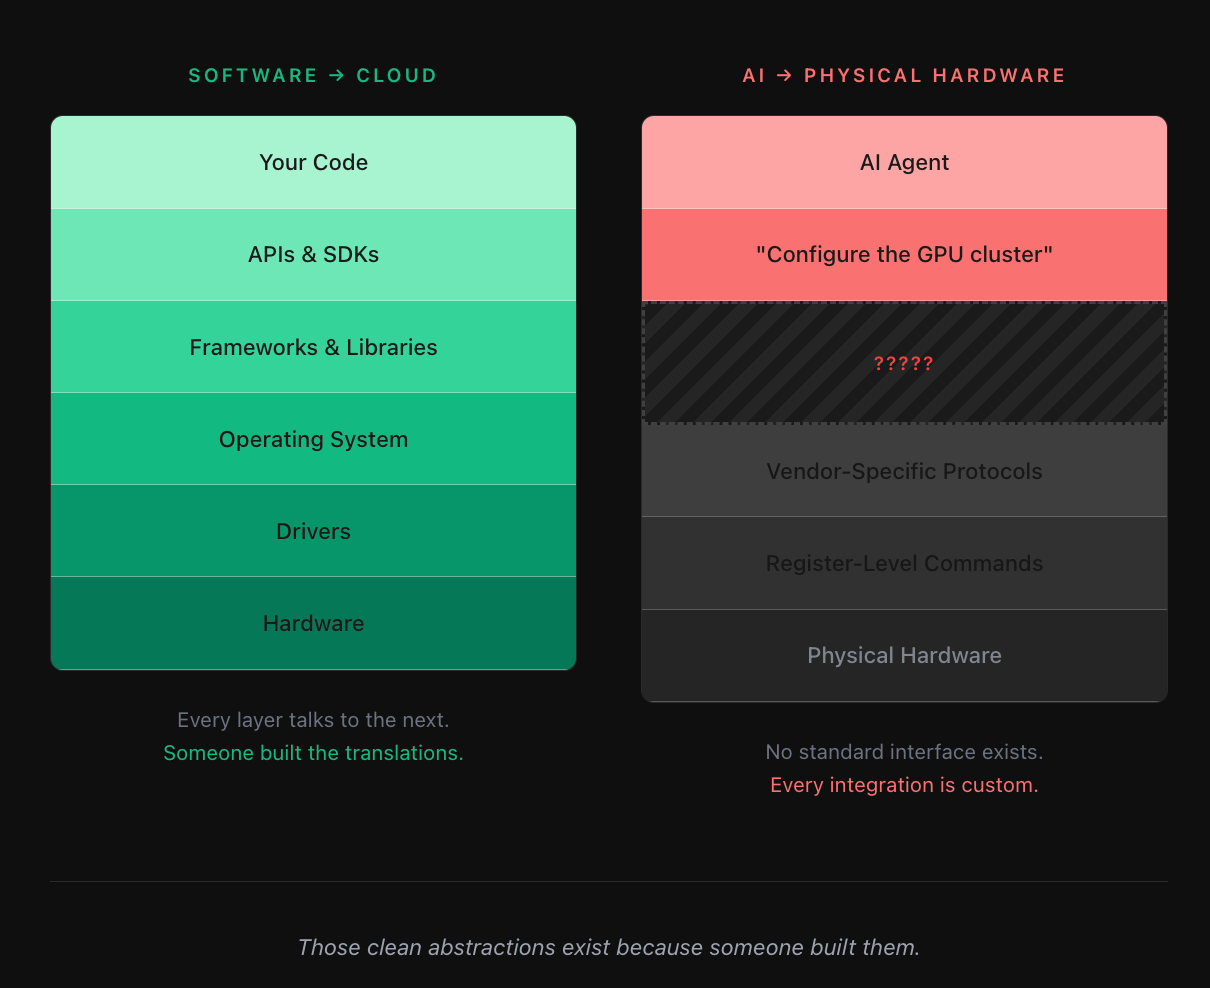
In the 1990s and 2000s, the internet scaled because engineers built these layers deliberately. Each one handled one job and exposed a clean interface to the layer above. Application developers didn’t need to understand routing or sockets. The whole system became modular, interchangeable, and efficient.
Hardware never got that treatment. The economics didn’t support it. Unlike software, where one protocol could serve millions of users, hardware is fragmented: different vendors, different chips, different protocols for different industries. Aerospace had its standards, automotive had its standards, industrial equipment had its standards. No single abstraction layer could serve all of them, and no single market was large enough to justify building one. Every integration is custom. Every deployment is bespoke.
So - the robotics company I mentioned? Their model worked perfectly when “hardware” meant an NVIDIA GPU in a data center. But their production robots used custom motor controllers, specific sensor chips, a particular FPGA configuration. Nobody at NVIDIA documented how to make those components play together. Nobody anywhere documented that. The knowledge existed in maybe fifty people worldwide, and those fifty people have job offers stacked to the ceiling.
The Same Problem at Every Scale
A data center and a robot look nothing alike. Different sizes, different environments, different purposes. But the engineering bottlenecks? Both require complex hardware configuration before they can do anything useful. The data center needs hundreds of components aligned and communicating. The robot needs dozens of processors initialized and calibrated. In both cases, the knowledge required to do this lives in documentation that is incomplete, outdated, or wrong.
The implication: any system that can reason about hardware configuration at data center scale can reason about it at the edge. The specific chips differ. The protocols differ. The underlying problem structure does not. What is required is an intelligence layer for hardware, wherever compute meets the physical world.
The $600 Billion Assumption
Let me frame the stakes differently.
Right now, the largest companies in the world are spending over $320 billion per year building AI infrastructure. With data centers, GPU clusters, networking equipment, power plants… estimates suggest this could exceed $500 billion in 2026.
The assumption behind this spending: AI will eventually generate returns that justify the investment.
But what that assumption requires: AI has to reach the physical world.
A language model that lives in the cloud generates value by producing text. But the much larger opportunity (the one that justifies hundreds of billions per year in capex) is AI that operates physical systems. Robots that work in factories, vehicles that drive themselves, data centers that configure themselves.
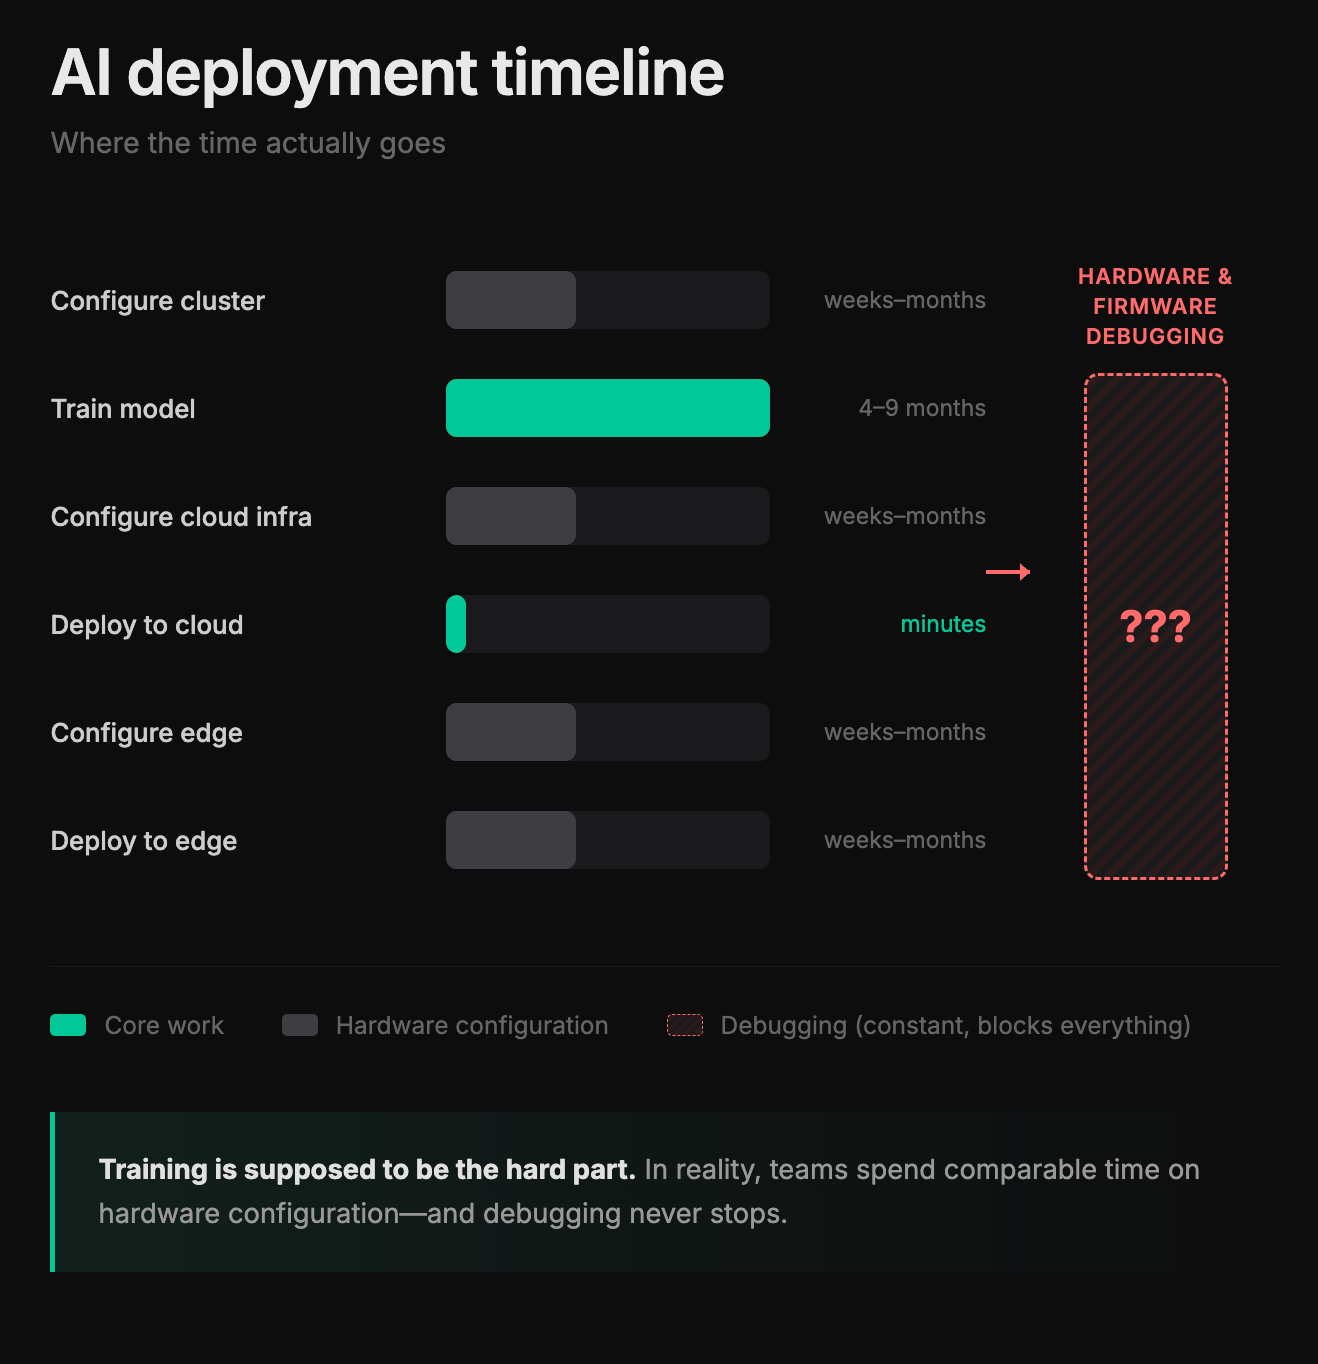
Every single one of those applications requires AI to cross the hardware boundary. And right now, that crossing looks like this:
Sequoia Capital’s David Cahn has been asking what he calls “AI’s $600 billion question”: where will the revenue come from to justify all this infrastructure spending?
The bottleneck isn’t compute or algorithms. The bottleneck is the last mile: getting software out of research environments and onto physical systems at scale. Data centers that need to configure thousands of heterogeneous servers. Automotive companies pushing models to vehicle fleets. Robotics startups deploying to factory floors. Aerospace programs integrating AI into flight systems. Every one of these deployments hits the same wall: The hardware boundary has no solution.
Why This Hasn’t Been Solved
The people who know how to deploy AI to hardware are approaching retirement age. They learned their craft on systems from the 1980s. They carry decades of hard-won intuition about failure modes and edge cases and undocumented behaviors.
The embedded systems engineering discipline has been supply-constrained for twenty years. Universities don’t produce enough graduates. The learning curve is brutal (5-7 years to senior competency). And 80% of embedded engineering job postings remain unfilled for months, sometimes years. The talent math:
↑ Physical AI investment: exponential growth, demand for hardware deployment expertise exploding
↓ Senior embedded engineers: flat to declining, retirements outpacing new graduates
↓ AI/ML engineers who understand hardware: rare and getting rarer, software culture dominates
↓ Documented best practices: fragmented across vendors, no standardization, no transferable knowledge
What Changes Everything
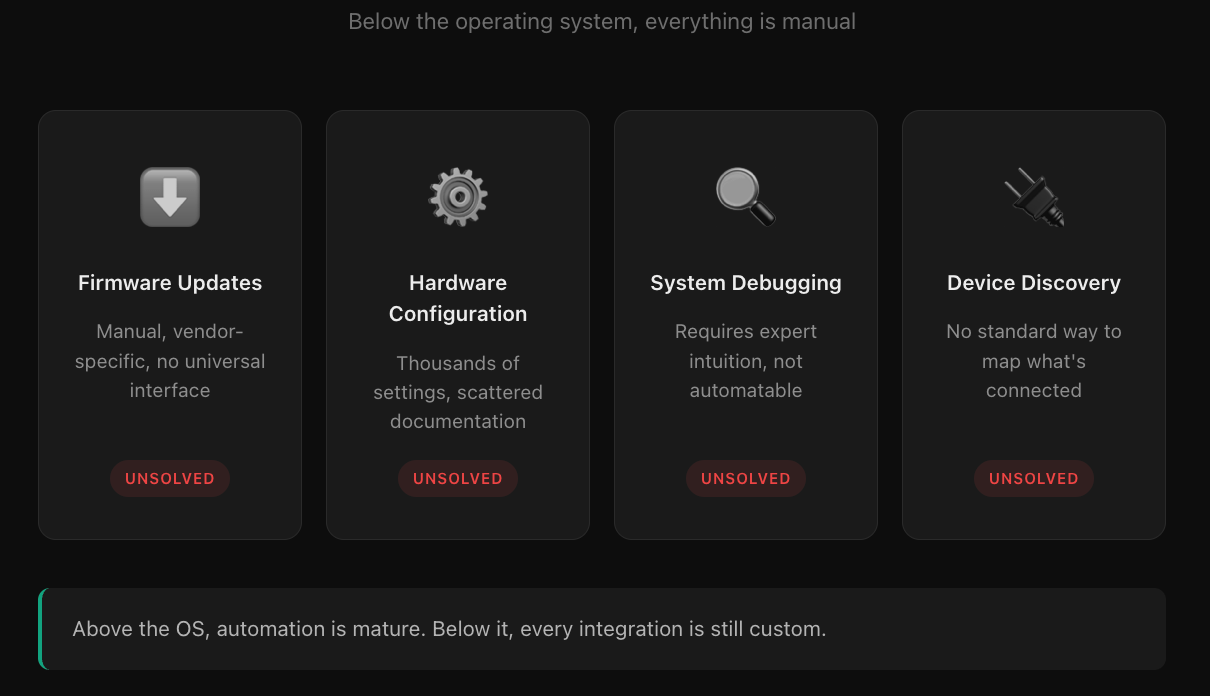
Hardware configuration has resisted automation for forty years because the work is investigative. Engineers read thousand-page datasheets, reason about unexpected behavior, and synthesize information across components that were never designed to work together, forming hypotheses and discovering the documentation was wrong.
The engineers who can do this are rare, and every data center, automotive and robotics company competes for the same small talent pool, while heterogeneous compute explodes the problem: systems now combine CPUs, GPUs, FPGAs, and custom ASICs, each with its own configuration surface. The bottleneck is a hard constraint on what organizations can build.
Rule-based automation never had a chance because the configuration space is too large, the edge cases too numerous, the documentation too unstructured for explicit knowledge encoding. Modern language models change the equation by reading datasheets the way an engineer does, tracking dependencies, reasoning about behavior. Two years ago this was impossible. But models hallucinate, and for mission-critical hardware, “usually right” is worthless.
Hardware offers ground truth. Unlike software, you can interrogate the physical system directly. This is embodied reasoning. The hard problem is maintaining coherent, multi-step reasoning while simultaneously controlling probes across dozens of protocols in real time, bidirectionally, on hardware that does not wait. The hard part is also building models that know how to do this, and gathering enough data to do it well.
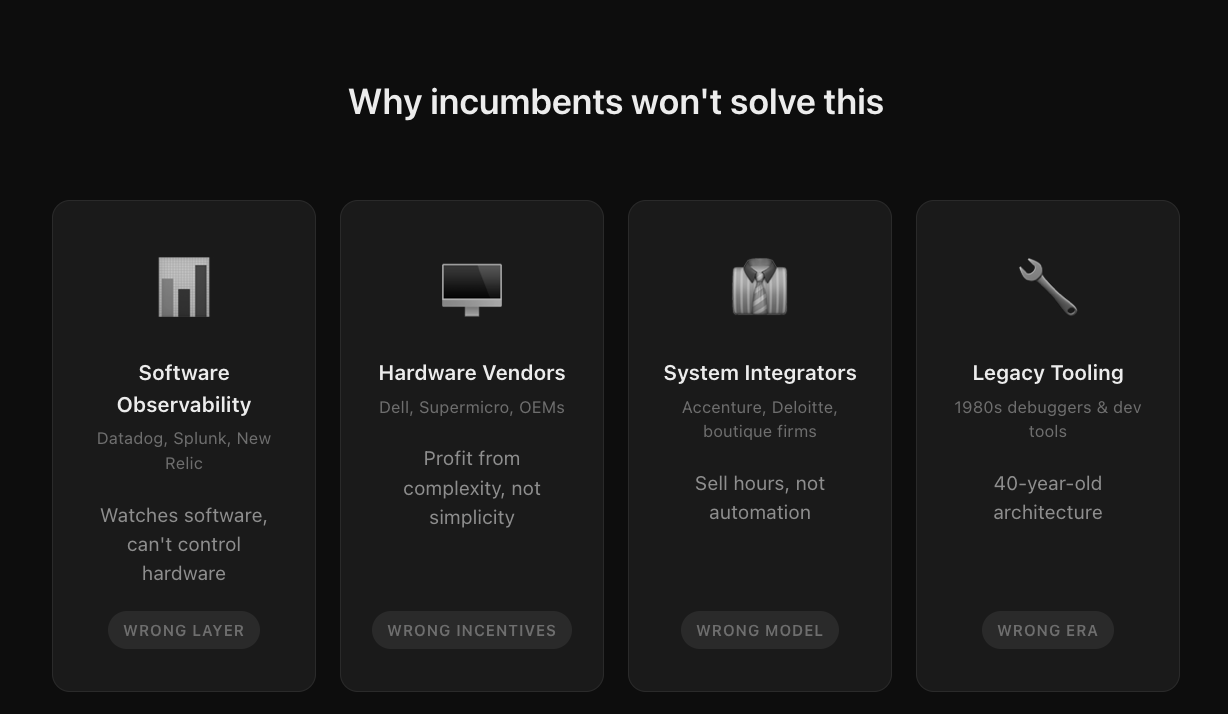
There’s a reason there’s only one CUDA. Despite billions invested, no one has successfully abstracted hardware at scale. Nvidia succeeded because they controlled both the hardware and the software stack, and spent two decades building the ecosystem. Everyone else tried to build the abstraction layer without the underlying data, without the hardware relationships, without the feedback loops. They failed.
This is why the system has to be two layers. One layer reasons over documentation and system state. One layer touches physical reality. Neither works alone.
What Comes Next
AI is moving from generating text to controlling machines. That transition bottlenecks at hardware.
But this constraint is starting to lift.
Organizations that could never afford six-month integration cycles can ship in weeks. Space programs that bottlenecked on three engineers who understood the full system can parallelize across teams. Robotics companies can iterate on hardware as fast as they iterate on software.
Every system that touches the physical world—data centers, satellites, autonomous vehicles, manufacturing lines—moves faster when hardware configuration stops being the long pole.
Hundreds of billions of dollars are flowing into physical AI and compute infrastructure. The returns depend on deploying that hardware, not just buying it. Deployment depends on configuration. Configuration depends on the engineers who understand it.
We need a system that learns hardware the way those engineers do, then scales what they know to every board, every rack, every factory floor.